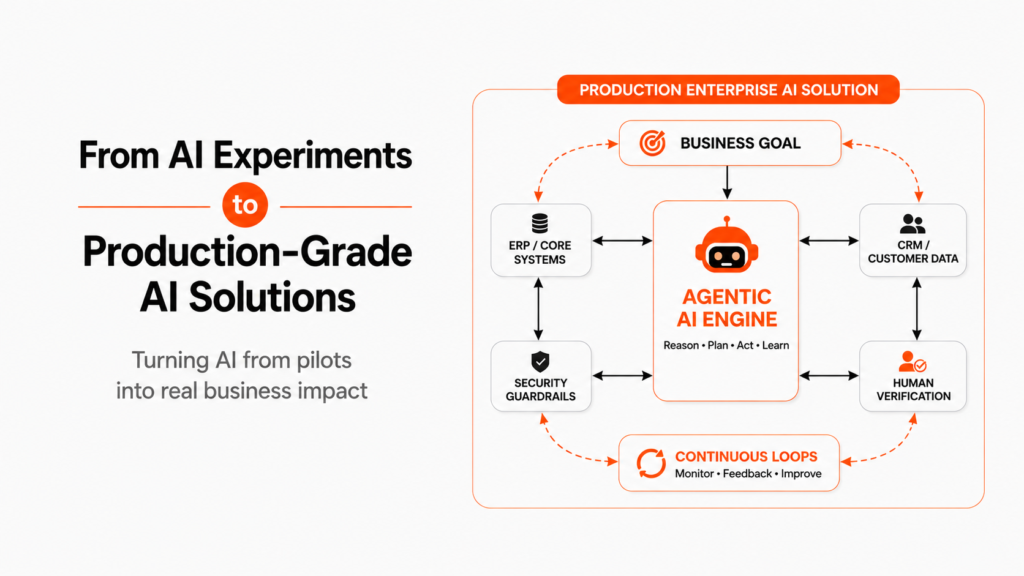
It’s quite easy to create a basic prototype of an AI agent, but when it comes to custom AI agent design, it takes more effort.
Unlike traditional software, AI agents deliver different results each time and they communicate with APIs, databases, and other systems. Just checking their outputs somewhere is not enough.
Without sufficient testing and evaluation the AI agents may get stuck in loops, make wrong decisions, or even include corrupted information in your database.
For this reason, companies need to have a system of automated testing of their AI agents.
As Jensen Huang’s “digital employees” vision:
“If the future workforce includes digital employees, then AI agents need to be evaluated like employees, not treated like software demos.”
This guide details a production-ready evaluation framework to benchmark tool call accuracy, validate plan trajectories, and secure reliable performance across complex enterprise workflows.
Unit Tests vs. Agent Evals: Architectural Comparison
To properly test AI agents, engineers need to go beyond traditional software testing. AI agents can handle complex tasks, use tools, and make decisions, so they need a different way of being tested.
| Testing Dimension | Traditional Unit Testing | LLM-as-a-Judge & Trajectory Evals |
| Testing Target | Tests individual functions and basic code. | Tests how the AI handles dynamic, multi-step tasks. |
| Assertion Type | Uses clear pass/fail rules, such as checking whether the output matches the expected result. | Uses different scoring criteria, usually on a scale from 0 to 1. |
| Input Constraints | Uses fixed inputs and structured JSON data. | Works with real user inputs and outputs from different tools. |
| System Visibility | Checks whether a function returns the expected result. | Tracks logs, tool usage, and changes in the agent’s state. |
| Failure Modes | Looks for coding errors and incorrect outputs. | Detects problems such as choosing the wrong tool, invalid JSON, schema errors, or losing context. |
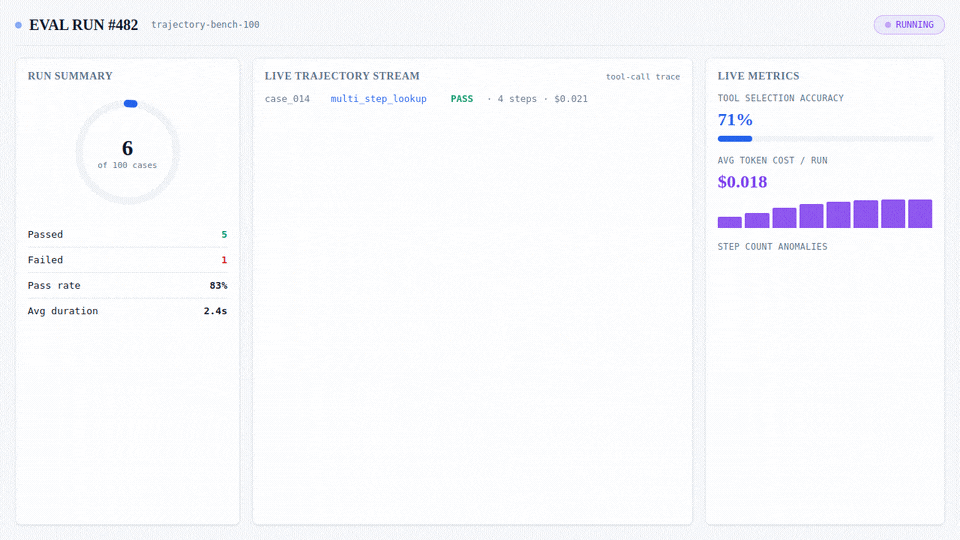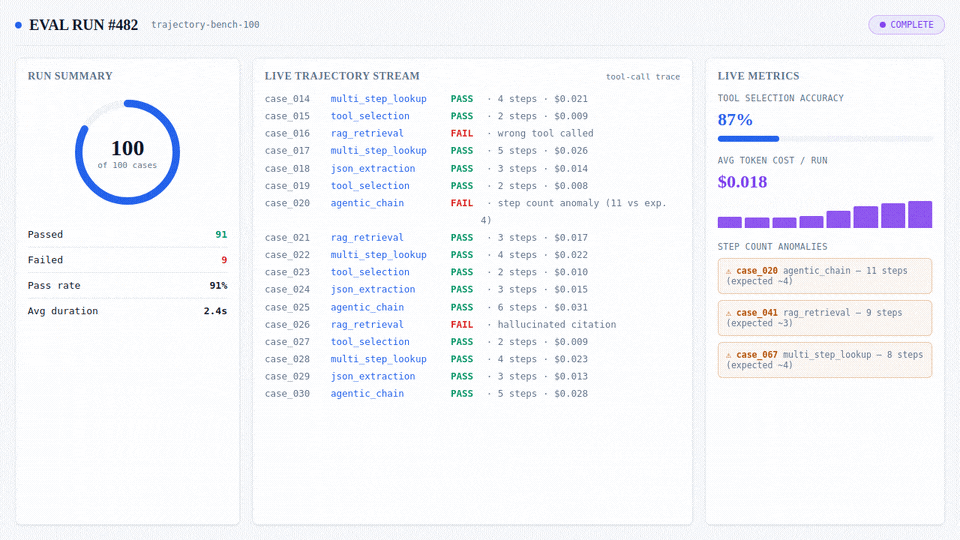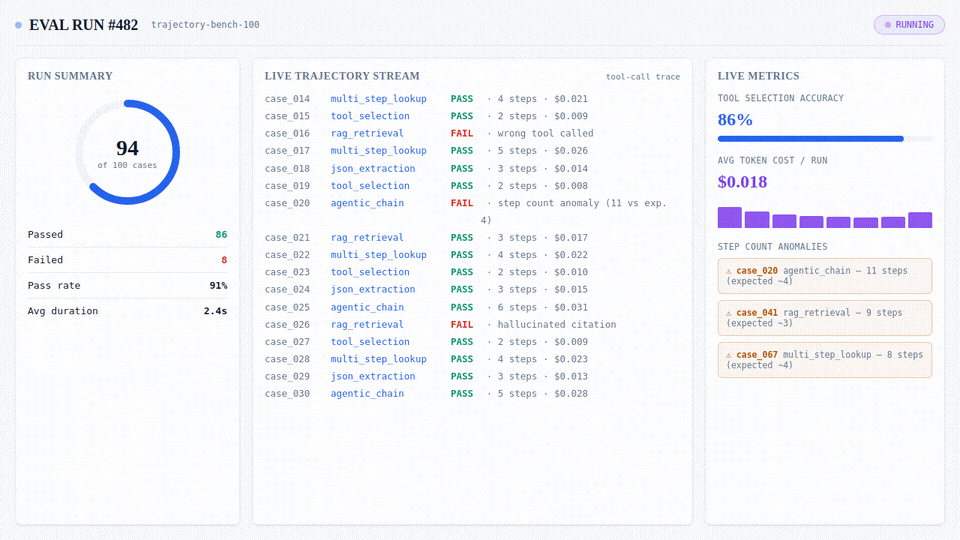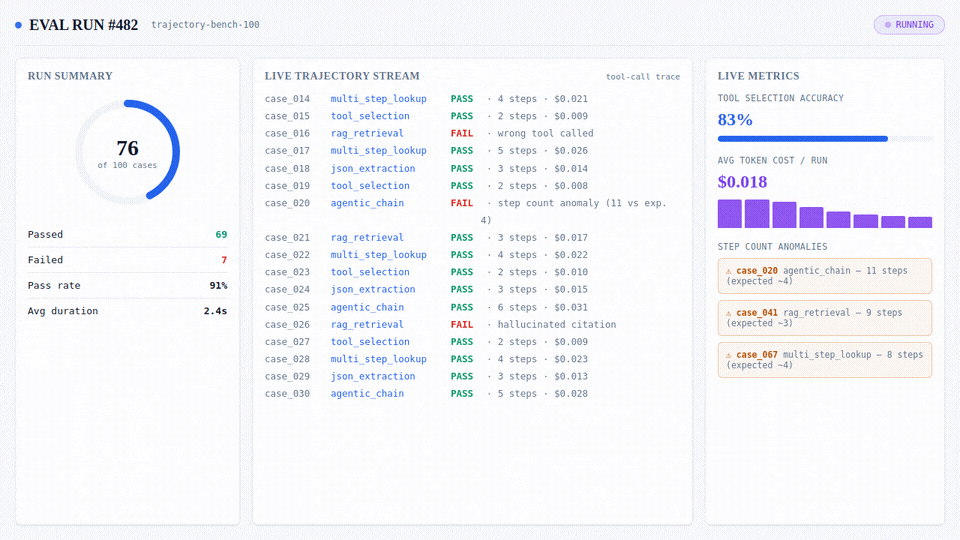
Assessing autonomous AI agents is different from evaluating a single prompt. It requires tracking the agent through multiple steps and continuously checking its performance:
- Trajectory Logging
Recording all intermediate steps, tool outputs, and environment results as the agent works. - Deterministic Verification
Checking JSON formats, HTTP response codes, and database changes using code-based checks. - Semantic Evaluation
Using lightweight LLM-as-a-Judge models to check the agent’s reasoning, tone, and ability to retrieve the right context. - Regression Testing
Using previous agent runs to test new prompts and check how changes to the underlying AI model affect performance.
The four layers of evaluation for AI agents
When creating a production-quality AI agent, four levels of assessment must be used to ensure optimal system performance.
Layer 1 – Tool Call & Schema Validation: In this layer, it is checked if the agent has used a proper API for the tool it needs to call has input the appropriate JSON parameters and respected the maximum number.
Layer 2 – Plan Efficiency: The calculations at this layer comprise counting every step of the execution; recording loops and avoiding overspending tokens.
Layer – 3 Business Process Validation: It allows checking whether the operations performed in the back end (e.g. updating CRM rows, processing refunds, etc.) conform to the expected rules of business.
Layer 4 – Compliance with Safety Regulations: The layer assesses the input and output to evaluate the agent’s ability to withstand attempts of jailbreak and whether it breaches the rules about data leakage and access rights.
💡 Is your engineering team struggling to validate non-deterministic agent workflows?
Stop guessing whether your system is production-ready. Book a Free 15-Minute Technical AI Audit with our lead systems architects to review your evaluation suite and benchmarking pipeline.
High-impact evaluation scenarios in Production Use Cases
Developing specialized evaluation datasets safeguards against undetected degradation of systems functioning in complex environments
1. Agents for finance and invoice reconciliation
The assessment of the systems operates ideally with important aspects like precision of state changes. Confirmations ensure that reconciliation agents do not change payment information unless relevant invoice items and purchase orders are presented.
2. Agents for customer service in multiple systems
The evaluation pipeline works on important features like efficiency of actions and preservation of context. Automated test systems allow real-time verification of customer account requests in Shopify or SAP systems to make sure that the system performs its functions without going in endless loops.
3. Agents for automated sales prospecting and scheduling
The assessment takes account of execution accuracy of a tool and adherence to safety measures. The test hybrid allows checking whether or not the agent defines calendar availability and schedules appointments correctly.
4. Agents for supply chain tracking and ERP dispatch
Evaluations work to verify that the APIs work and to assess the capability of the agent in unusual situations.
When we engineered production pipelines for mid-market clients, we helped a mid-market enterprise cut manual invoice processing costs by 60% while maintaining human-in-the-loop validation across core databases.
The Engineering Roadmap to Implement Agent Evals
Building a scalable evaluation harness requires integrating continuous testing directly into your deployment cycle.
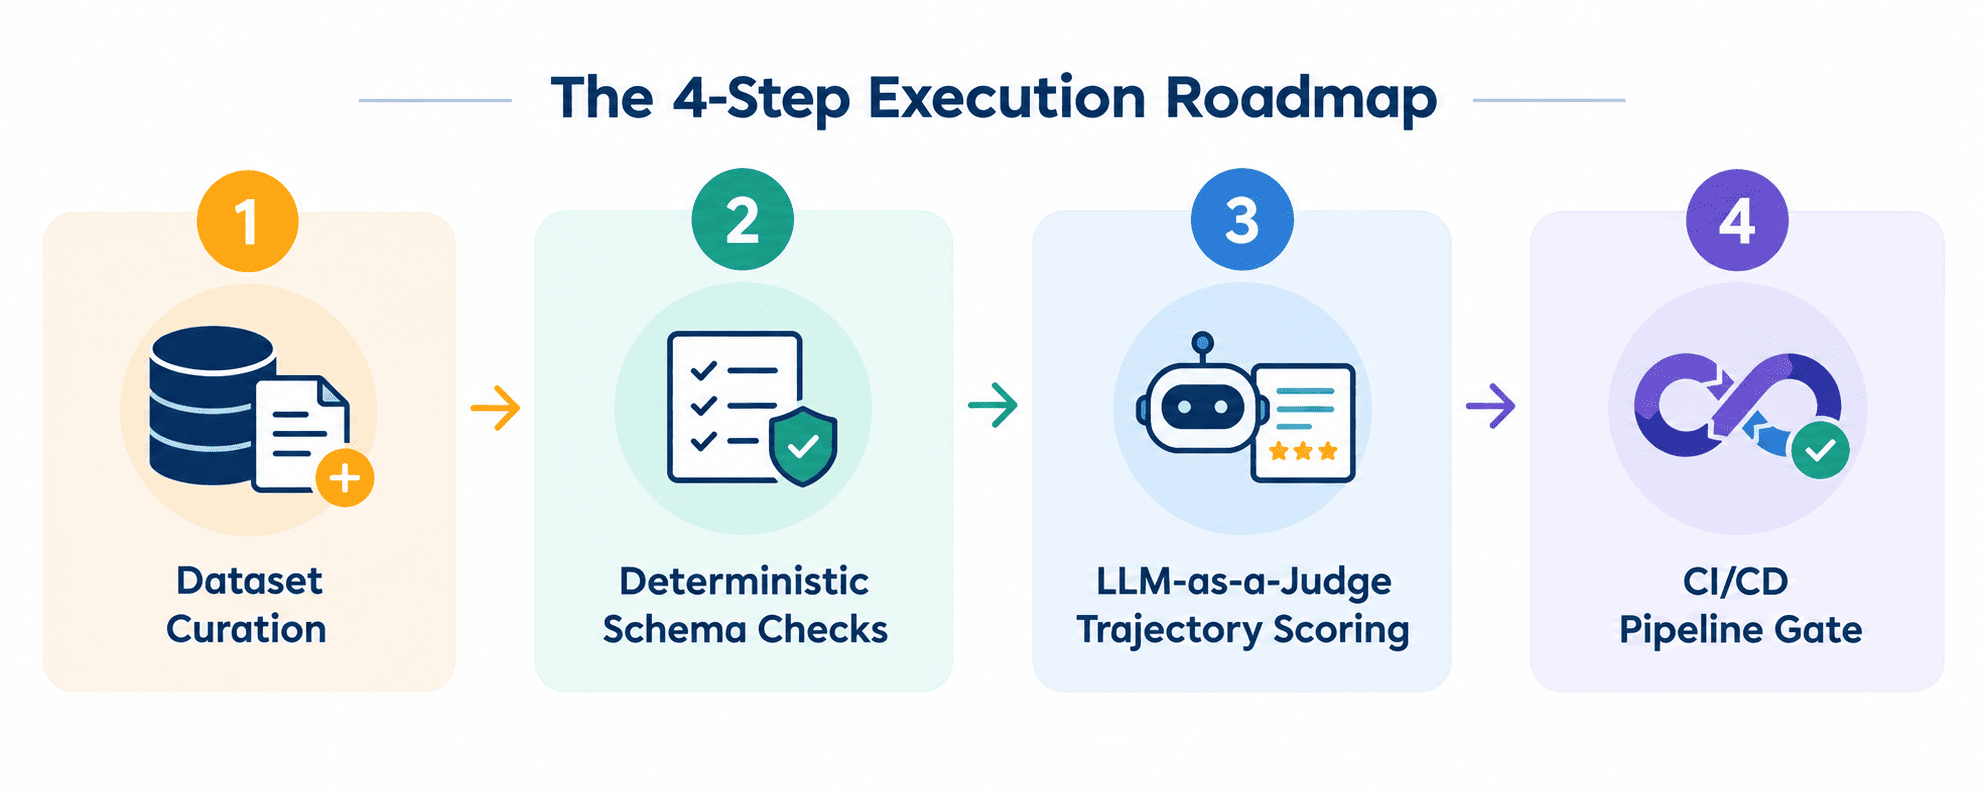
Phase 1: Prepare Golden Trajectory Data Sets
Gather 50 to 100 valid running paths. Be sure to include rare events such as edge cases, wrong inputs and APIs errors. These running paths should be treated as immutable regression datasets.
Phase 2: Create Deterministic Verification Hooks
Use code-level verification to build checks with libraries like Pydantic or Zod to fix JSON schema validation for all inputs.
Phase 3: Launch LLM-as-Judge Evaluation Methodologies
Set up fast LLMs that comply with strict rubrics in order to verify qualitative criteria of reasoning correctness and courtesy when dealing with clients
Phase 4: Implement Evals in CI/CD Gateways
Introduce automated evaluation mechanism in GitHub Actions or GitLab CI. Ensure that prompt or code enhancements cannot be permitted until the evaluation thresholds have been achieved. If you are interested in getting more specifics on setting up first enterprise AI project, please refer to our guide.
🚀 Build Production-Grade Agentic Systems
Ready to deploy secure, thoroughly evaluated agent workflows across your enterprise stack?
Risk Mitigation Strategies: Cost, Latency, and Test Flakiness Management
Automated evaluation deployments pose some technical operational obstacles that must be solved by team leaders:
- LLM-as-a-Judge Cost Inflation: Executing large evaluator models for each code commit leads to high expenses. Instead, apply distilled smaller models for routine checks and make use of cutting-edge models for night runs.
- Evaluation Flakiness: Non-deterministic evaluator output causes unstable test runs. Set the temperature to zero during evaluator calls and make use of structured output schemas in order to make evaluations more reliable.
- Overfitting to Golden Datasets: Agents are prone to overfit on narrow benchmarking inputs. Therefore, constantly maintain your golden testing data by using anonymized production traces and keep up with the changes in traffic patterns.
Frequently Asked Questions (FAQs)
Model evals evaluate the base model’s proficiency through separate metrics, such as MMLU and GSM8K. Agent evals check the whole system, which includes prompts, memory modules, tool APIs, and orchestration mechanisms, to see how successfully it performs tasks in dynamic conditions.
LLM-as-a-Judge is an evaluation procedure according to which a different model evaluates the reasoning process, different actions, or end result of the agent according to a would-be rubric.
The standard evaluation set consists of 50-100 well-assembled test cases.
Absolutely. Systems like PyTest or Jest conduct deterministic evaluations (which may include checking the JSON schema, API codes, and timing) as well as use special evaluations for agent evals.
Master Custom AI Agent Development with Robust Evals
Moving AI agents from prototypes to production requires proper testing and monitoring. Automated checks and clear safety controls help teams deploy AI agents with confidence.
Ready to build governed, production-ready agentic architectures for your business?